Appendices
Appendix G
Croissant Appendix
Author Contributions and Acknowledgements
In our efforts of transparency, we provide a summary of contributions for all authors and persons associated to the paper. Manuel, Patrick, Nuno, and Pierre belong to the core team and have participated throughout all steps of the project, from decision-making to report writing. Manuel coordinated the project and led the data collection, design decisions, and model evaluation efforts, and strongly participated in the model training. Pierre is the senior author of the project and was instrumental through constant feedback, project coordination, securing the compute grant, and design decisions. Patrick led the scaling law efforts and spearheaded the model training on distributed compute clusters. Nuno led the Chat and translation finetuning efforts, including constructing model finetuning pipelines and datasets, and gave constant feedback throughout the project. Pedro provided help on the development of the pre-training codebase and gave feedback on the pre-training stream of the work. João and Ricardo constructed the parallel data used for pre-training, which included efforts in both large-scale data collection and filtering. Duarte assisted with the fine-tuning efforts. António worked on base model finetuning on specific tasks and was in charge of the Chat model evaluation and the inference speed benchmark. Caio assisted with data collection efforts and provided high-quality, extensive feedback and notes on the report. Nicolas assisted with data collection efforts and data scrapping. Antoni adapted the model to swiftly run on mobile devices. Gautier, Céline, François, André are senior researchers who provided valuable feedback and important guidance throughout the project and were instrumental in obtaining compute grants.
This work is a collaboration of academic and industrial partners. On the academic side, core authors are affiliated with CentraleSupélec (Université Paris Saclay) and Instituto Superior Técnico de Lisboa, and other contributors are linked to Sorbonne Université and Imperial College London. On the industrial side, core authors receive funding from respectively Illuin Technology (Paris), Unbabel (Lisboa), Equall (New York, Lisboa, Paris). Training compute is obtained on the Jean Zay supercomputer operated by GENCI IDRIS through compute grant 2023-AD011014668R1 as well as on Adastra through compute grant AD010614770. Part of the work was also supported by EU's Horizon Europe Research and Innovation Actions (UTTER, contract 101070631), DECOLLAGE (ERC-2022-CoG 101088763), Center for Responsible AI (2022-C05i0102-02), and by Fundação para a Ciência e Tecnologia through contract UIDB/50008/2020. Evaluation and finetuning experiments are done on the Ruche platform (Université Paris Saclay), as well as on privately owned compute centers.
Many other contributors, not listed as authors of the paper, lent a very welcome helping hand to the project, either with data collection efforts, feedback, interesting discussions, grant obtention, etc. In no particular order, we extend our thanks to Hélène Rousset, Bruno Hays, Bilel Omrani, Sacha Muller, Elena Hinnekens and Robert Vesoul (Illuin Technology), Paul-Henry Cournède, Renaud Monnet, Géraud Faye (CentraleSupélec), Pierre-Etienne Devineau (DINUM), Louise-Anne Charles (BnF Datalab), the Unbabel TowerLLM team. Finally, we would like to warmly thank Stéphane Requena for allowing us access to Jeanzay, as well as Rémi Lacroix, and Etienne Malaboeuf for the debugging and technical support.
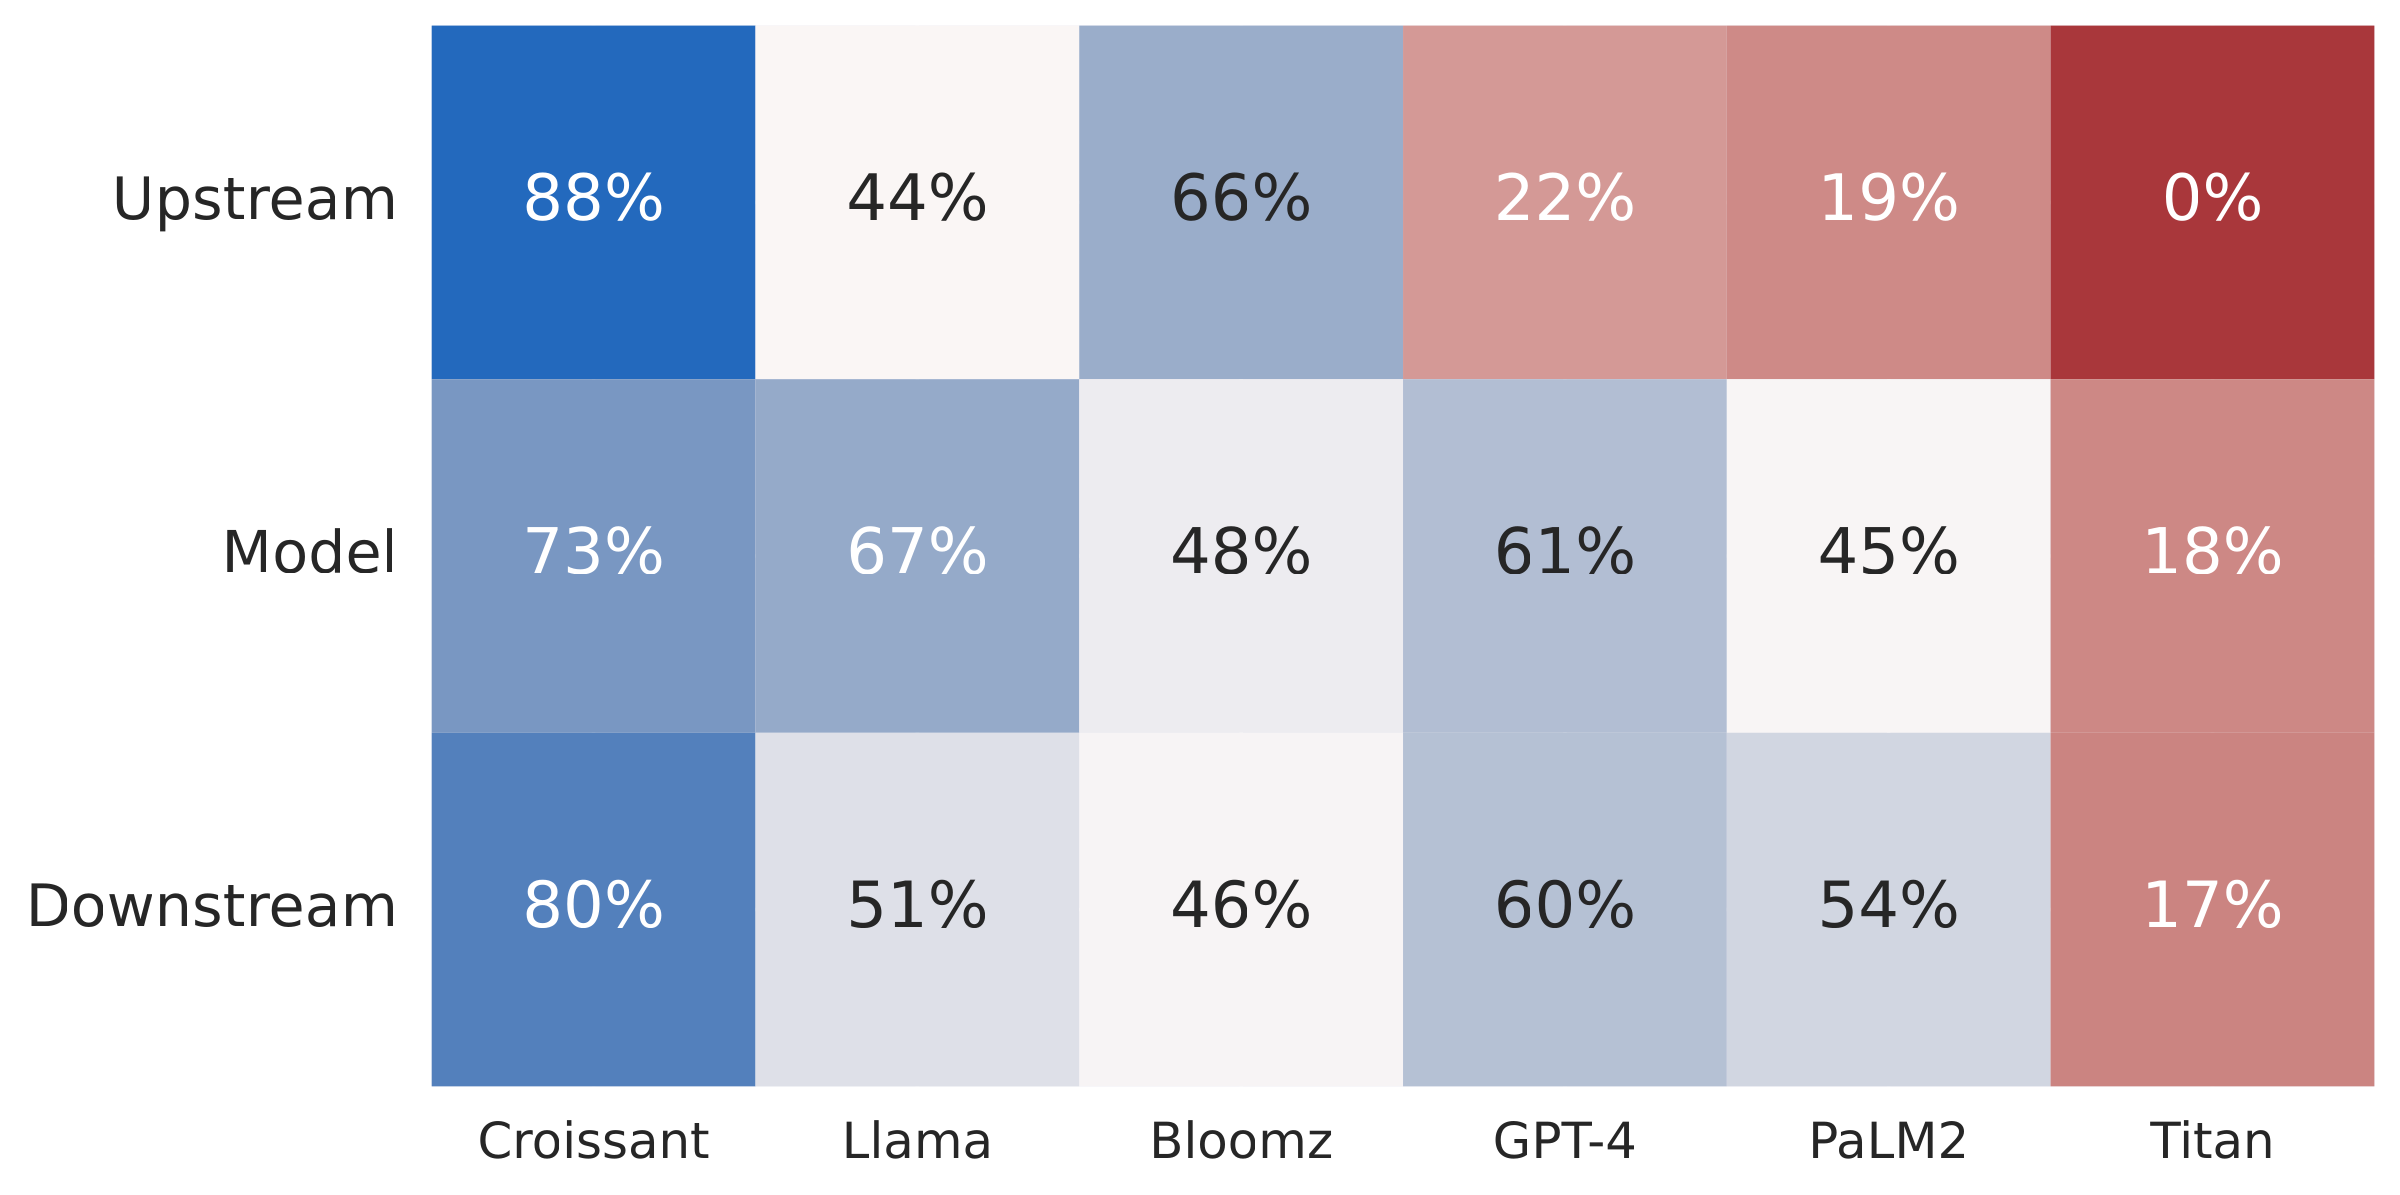
FMTI
Disclaimers and Methodology
The FMTI grid is meant to assess Foundation Models, but base models and models that were fine-tuned on instruction or chat datasets imply different training, evaluation and data curation protocols, thus largely modifying their assessment through the FMTI. Training an instruction or chat model from a base model is a process that has recently been completely democratized through the use of crowdsourced or synthetic datasets, and individuals are now fully capable of finetuning their own model variants in a variety of manners. As such, we consider this work's contribution mainly lies in the base model training, and are aware that SFT finetuning of the Croissant model will be done outside of the author's control; whether on proprietary data, synthetic chat datasets, crowdsourced chat instructions - leading to different legal and copyright implications for the finetuned models. We thus focus on the base model in our evaluation and give the complete criteria list as detailed in the appendix.
Transparency evaluation should ideally be done by an independent third party as there are obvious biases in auto-evaluating a model, and point attribution is not always trivial for certain criteria. As such, we take a rather conservative approach to point attribution and detail our process in an open document. Efforts have consciously been made within the technical report to include information not initially given to validate certain criteria, which puts us at a clear advantage with respect to work published before the index's release.
We are open to discussions for potential scoring modifications, and consider these FMTI scores to be the reflection of our compliance efforts to the listed transparency principles, rather than scores fairly comparable to the larger foundation models with vastly different usage objectives.
Additional data details
French Data
Refer to Table 1.
| Dataset | Size (GB) | Documents | Tokens (M) | Token/Doc |
| CulturaxFr | 1216.03 | 363197906 | 292833.75 | 806.14 |
| WikisourceFr | 10.84 | 2557238 | 2699.00 | 1055.44 |
| Wikipedia20231101.fr | 7.37 | 2563646 | 2002.51 | 781.12 |
| JadeOpendata | 5.19 | 550065 | 1295.29 | 2354.79 |
| JorfOpendata | 3.83 | 3189949 | 967.10 | 303.17 |
| LegiOpendata | 3.56 | 2151510 | 816.44 | 379.47 |
| AccoOpendata | 3.39 | 251332 | 758.15 | 3016.52 |
| IncaOpendata | 2.60 | 369687 | 627.32 | 1696.90 |
| ProjectgutenbergFr | 0.97 | 2447 | 301.19 | 123086.16 |
| CappOpendata | 0.91 | 71949 | 247.14 | 3434.97 |
| CustomLayoutDatasetTextOnly | 0.77 | 291604 | 191.11 | 655.38 |
| DebatsOpendata | 0.77 | 2114 | 149.09 | 70524.31 |
| CassOpendata | 0.76 | 140803 | 206.04 | 1463.35 |
| KaliOpendata | 0.68 | 402963 | 152.33 | 378.01 |
| SwissLegislation | 0.26 | 11086 | 68.33 | 6163.81 |
| FrenchOpenSubtitles | 0.15 | 5379 | 41.84 | 7779.26 |
| CnilOpendata | 0.12 | 15168 | 26.37 | 1738.72 |
| BnfClean2023 | 0.10 | 341 | 27.04 | 79295.71 |
| QrOpendata | 0.10 | 530 | 21.73 | 41005.03 |
| SardeOpendata | 0.09 | 221278 | 28.10 | 127.01 |
| DoleOpendata | 0.08 | 4000 | 19.36 | 4839.07 |
| ConstitOpendata | 0.07 | 6977 | 15.27 | 2188.28 |
| FrenchLibrispeechTextOnly | 0.06 | 255631 | 12.91 | 50.49 |
| FrenchPodcasts | 0.01 | 1237 | 1.56 | 1259.90 |
| FrenchPoetry | 0.00 | 1721 | 0.76 | 441.23 |
| Train | 1258.70 | 376266561 | 303509.73 | 806.63 |
English data
Refer to Table 2.
| Dataset | Size (GB) | Documents | Tokens (M) | Token/Doc |
| SlimPajama | 2333.77 | 590194779 | 630441.67 | 1068.19 |
| Project Gutenberg PG19 | 10.67 | 28602 | 23580.49 | 824435.00 |
| Gutenberg Canaries | 2.75 | 7515 | 555.40 | 73905.01 |
| Train | 2351.13 | 591230543 | 655637.48 | 1108.94 |
Code data
Refer to Table 3.
| Dataset | Size (GB) | Documents | Tokens (M) | Token/Doc |
| StarcoderdataJava | 82.49 | 20061773 | 29740.73 | 1482.46 |
| StarcoderdataJavascript | 61.64 | 19534285 | 24546.60 | 1256.59 |
| StarcoderdataPython | 57.00 | 12856649 | 24605.09 | 1913.80 |
| StarcoderdataC | 50.60 | 8526791 | 15791.76 | 1852.02 |
| StarcoderdataCpp | 45.84 | 6343527 | 19607.90 | 3091.01 |
| PypiClean | 29.20 | 2428172 | 12120.74 | 4991.72 |
| StarcoderdataSql | 10.38 | 965666 | 3278.24 | 3394.80 |
| StarcoderdataJupyterScriptsDedupFiltered | 6.67 | 905365 | 2567.77 | 2836.18 |
| StarcoderdataJupyterStructuredCleanDedup | 5.55 | 662056 | 2119.72 | 3201.72 |
| StarcoderdataJson | 5.43 | 4741547 | 2165.87 | 456.79 |
| StarcoderdataTex | 4.86 | 517551 | 1916.88 | 3703.76 |
| StarcoderdataShell | 2.98 | 2196327 | 1178.17 | 536.43 |
| CodeContests | 2.79 | 1485888 | 1228.61 | 826.85 |
| StarcoderdataCuda | 0.52 | 57570 | 227.24 | 3947.14 |
| GithubJupyterCodeToText | 0.48 | 46978 | 159.49 | 3395.09 |
| StarcoderdataDockerfile | 0.41 | 565791 | 161.48 | 285.41 |
| StarcoderdataIdris | 0.03 | 7942 | 11.72 | 1475.09 |
| Train | 366.87 | 81903878 | 141428.02 | 1726.76 |
Parallel data
Refer to Table 4.
| Dataset | Size (GB) | Documents | Tokens (M) | Token/Doc |
| CustomFrEn | 113.35 | 407858836 | 35641.60 | 87.39 |
| ThesesFr20132023 | 0.36 | 95009 | 81.60 | 858.91 |
| OriginalSongsLyricsWithFrenchTranslation | 0.20 | 75020 | 53.48 | 712.93 |
| Train | 113.91 | 408028865 | 35776.69 | 87.68 |
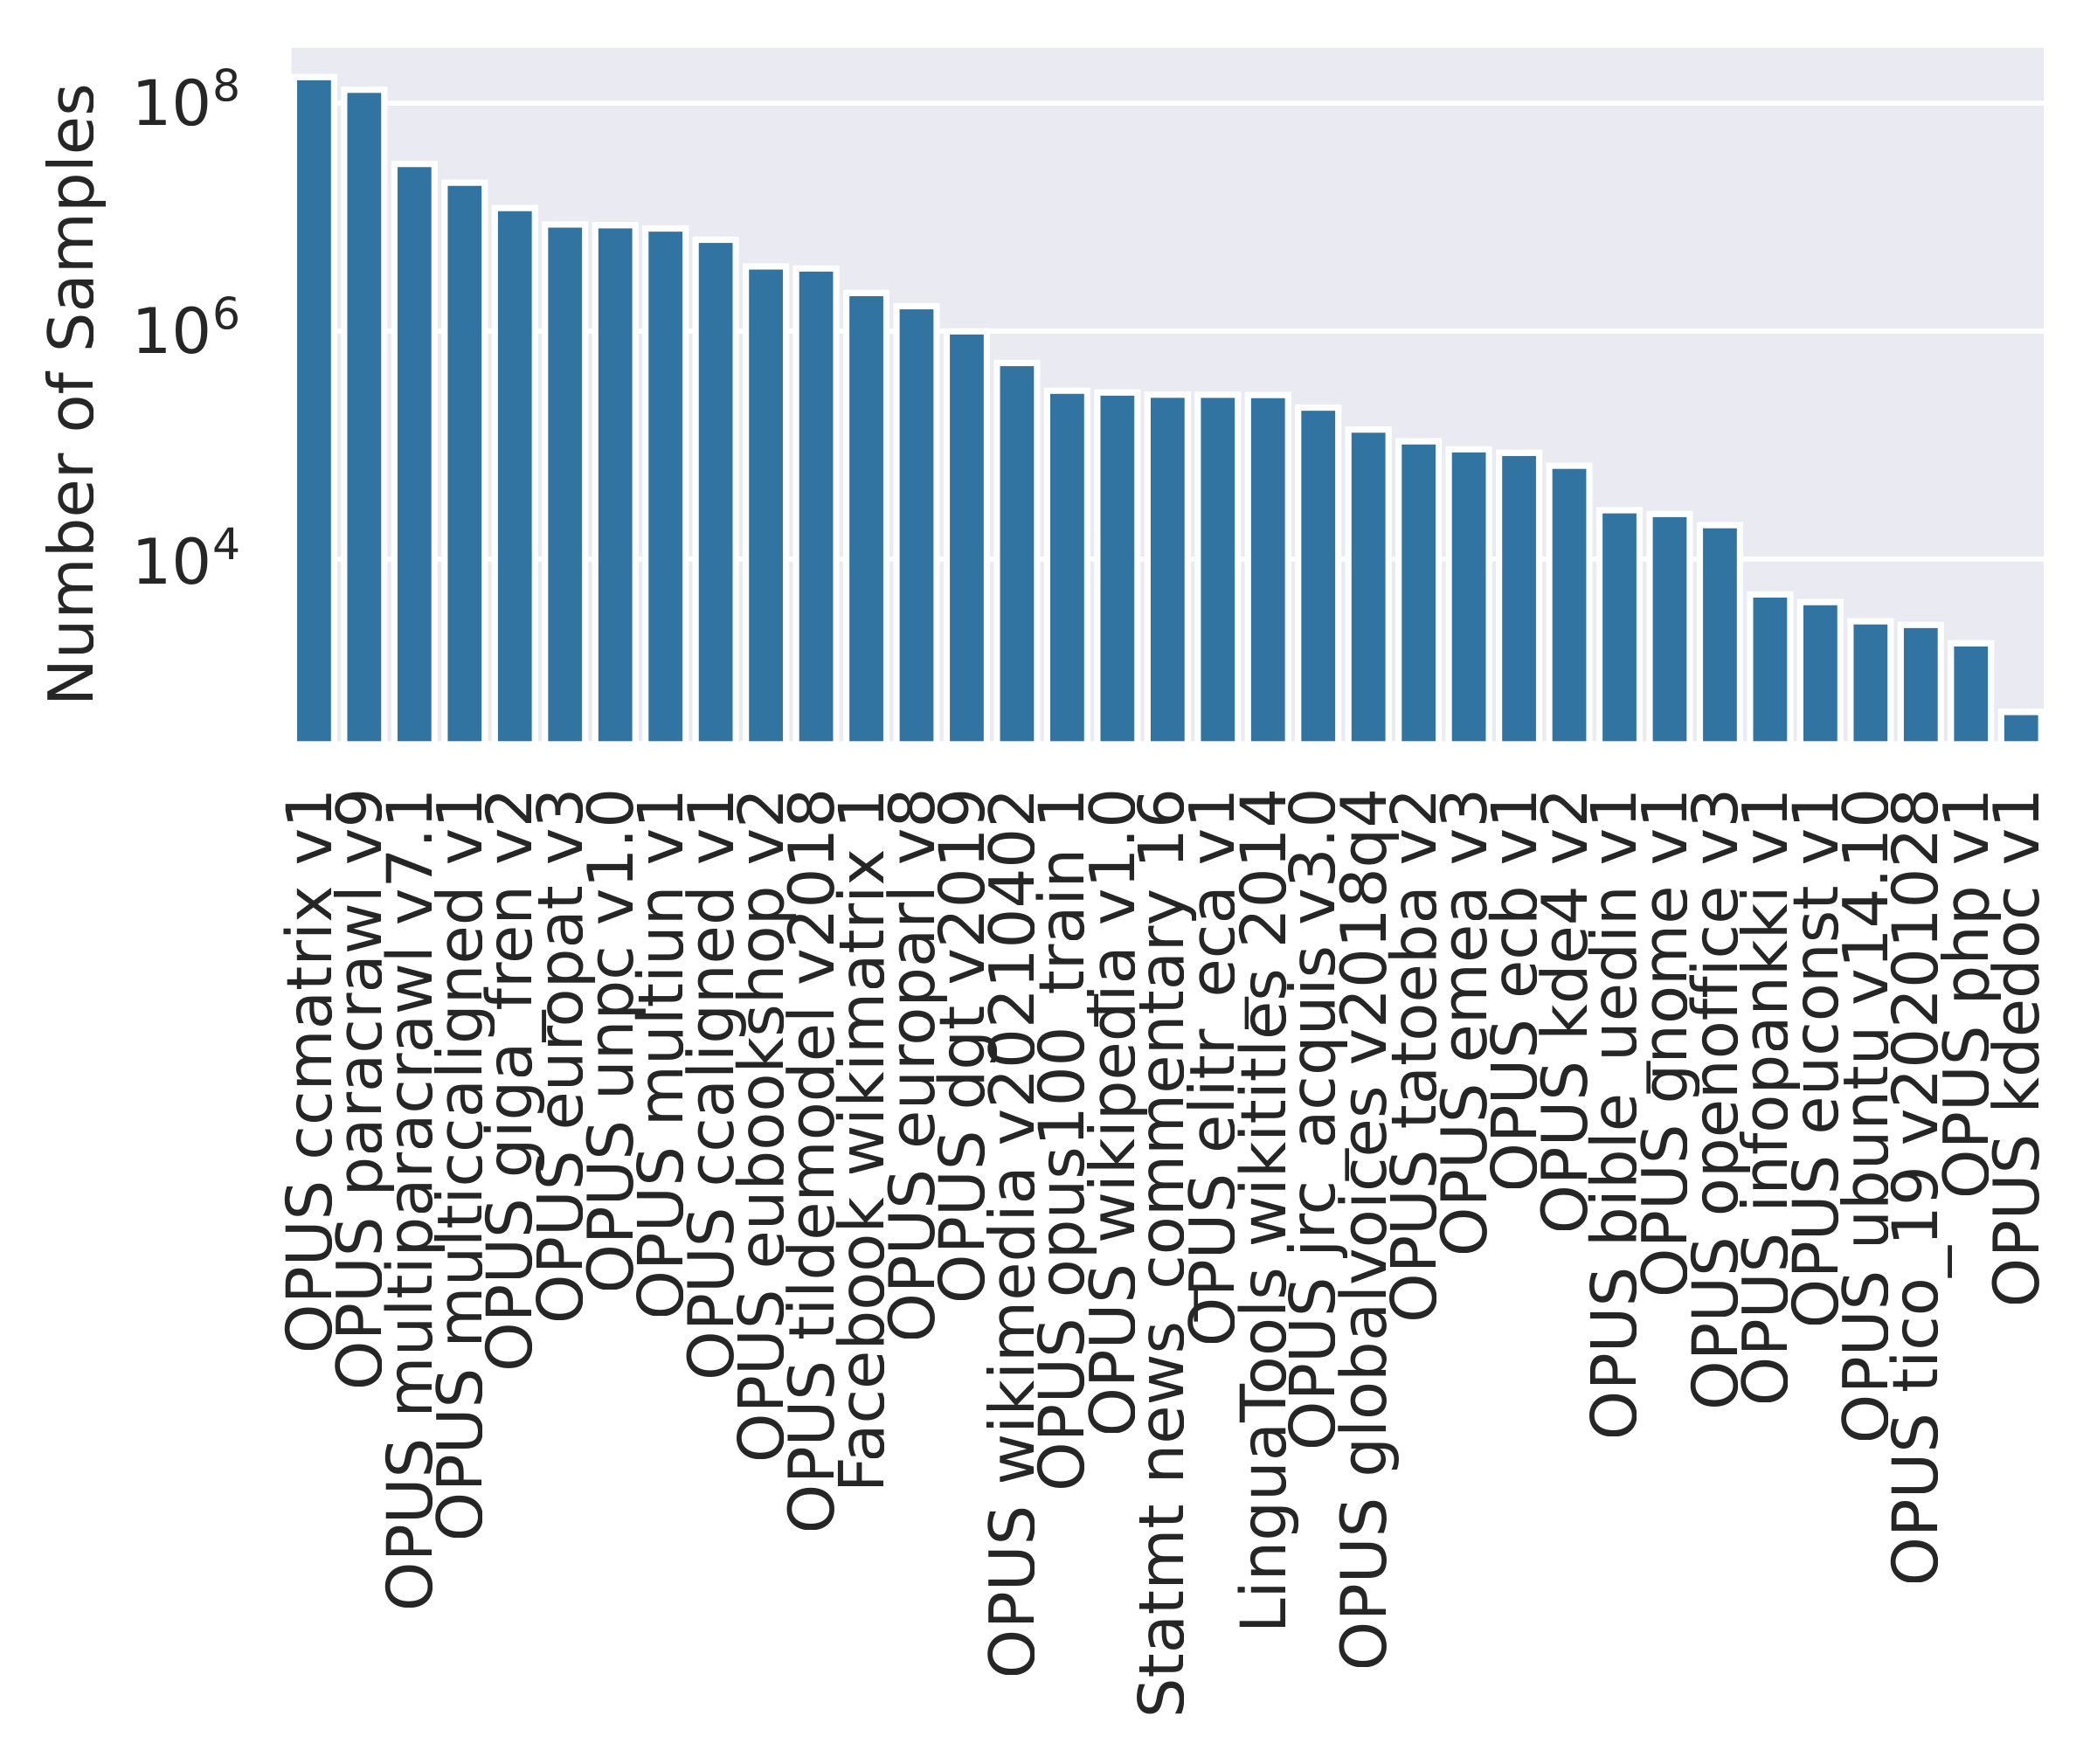
OPUS data distribution is given in Figure 2.
Scaling Law Corpus
For the scaling law experiments, we use a smaller subsampled dataset, consisting of splits of French, English, and Code data we vary in ratio to study the impact of language distribution. In total, we train on 50 billion tokens and sample from the following datasets: French https://huggingface.co/datasets/manu/french-30b, English https://huggingface.co/datasets/manu/english-60b and Code https://huggingface.co/datasets/manu/code_20b. In all datasets, a breakdown of the sources is given in the dataset_stats.csv file at the root of the data folder. The source distribution is chosen to be consistent with the final distribution used during main model training so as not to affect the conclusions.
Chat examples
The following results were not cherry-picked and were generated with a temperature of 0.5, a Top-P of 0.95 and a Top-K of 40. They focus on Writing tasks which CroissantLLM is best at.
Translation
Travel Advice
Cover Letter
Code Generation
Safety Response
Results
Methodology
Base models are evaluated through the LM Evaluation harness framework . For classification tasks, we choose the answer with the largest log likelihood when concatenated with the prompt, as is implemented within the framework.
For generative tasks, we simply generate with the default settings, which is greedy sampling. We acknowledge CroissantLLM works best with higher temperature values but did not want to introduce stochasticity to the evaluation. We also limit each benchmark task to 5000 samples at most, to shorten evaluation time. All evaluations are reproducible through the code at https://github.com/EleutherAI/lm-evaluation-harness.
MT-Bench
Turn 1 (Figure 3) and Turn 2 (Figure 4) results are shown. We notice that small models struggle with reasoning-based tasks and constrained generation imposed by Turn 2 prompts. Figures 5 and 6 compare our results on small language models to other common bigger models. Results in French for models with sizes over 7B parameters were extracted from https://huggingface.co/datasets/bofenghuang/mt-bench-french and results in English are from https://huggingface.co/spaces/lmsys/mt-bench/tree/main/data/mt_bench/model_judgment.
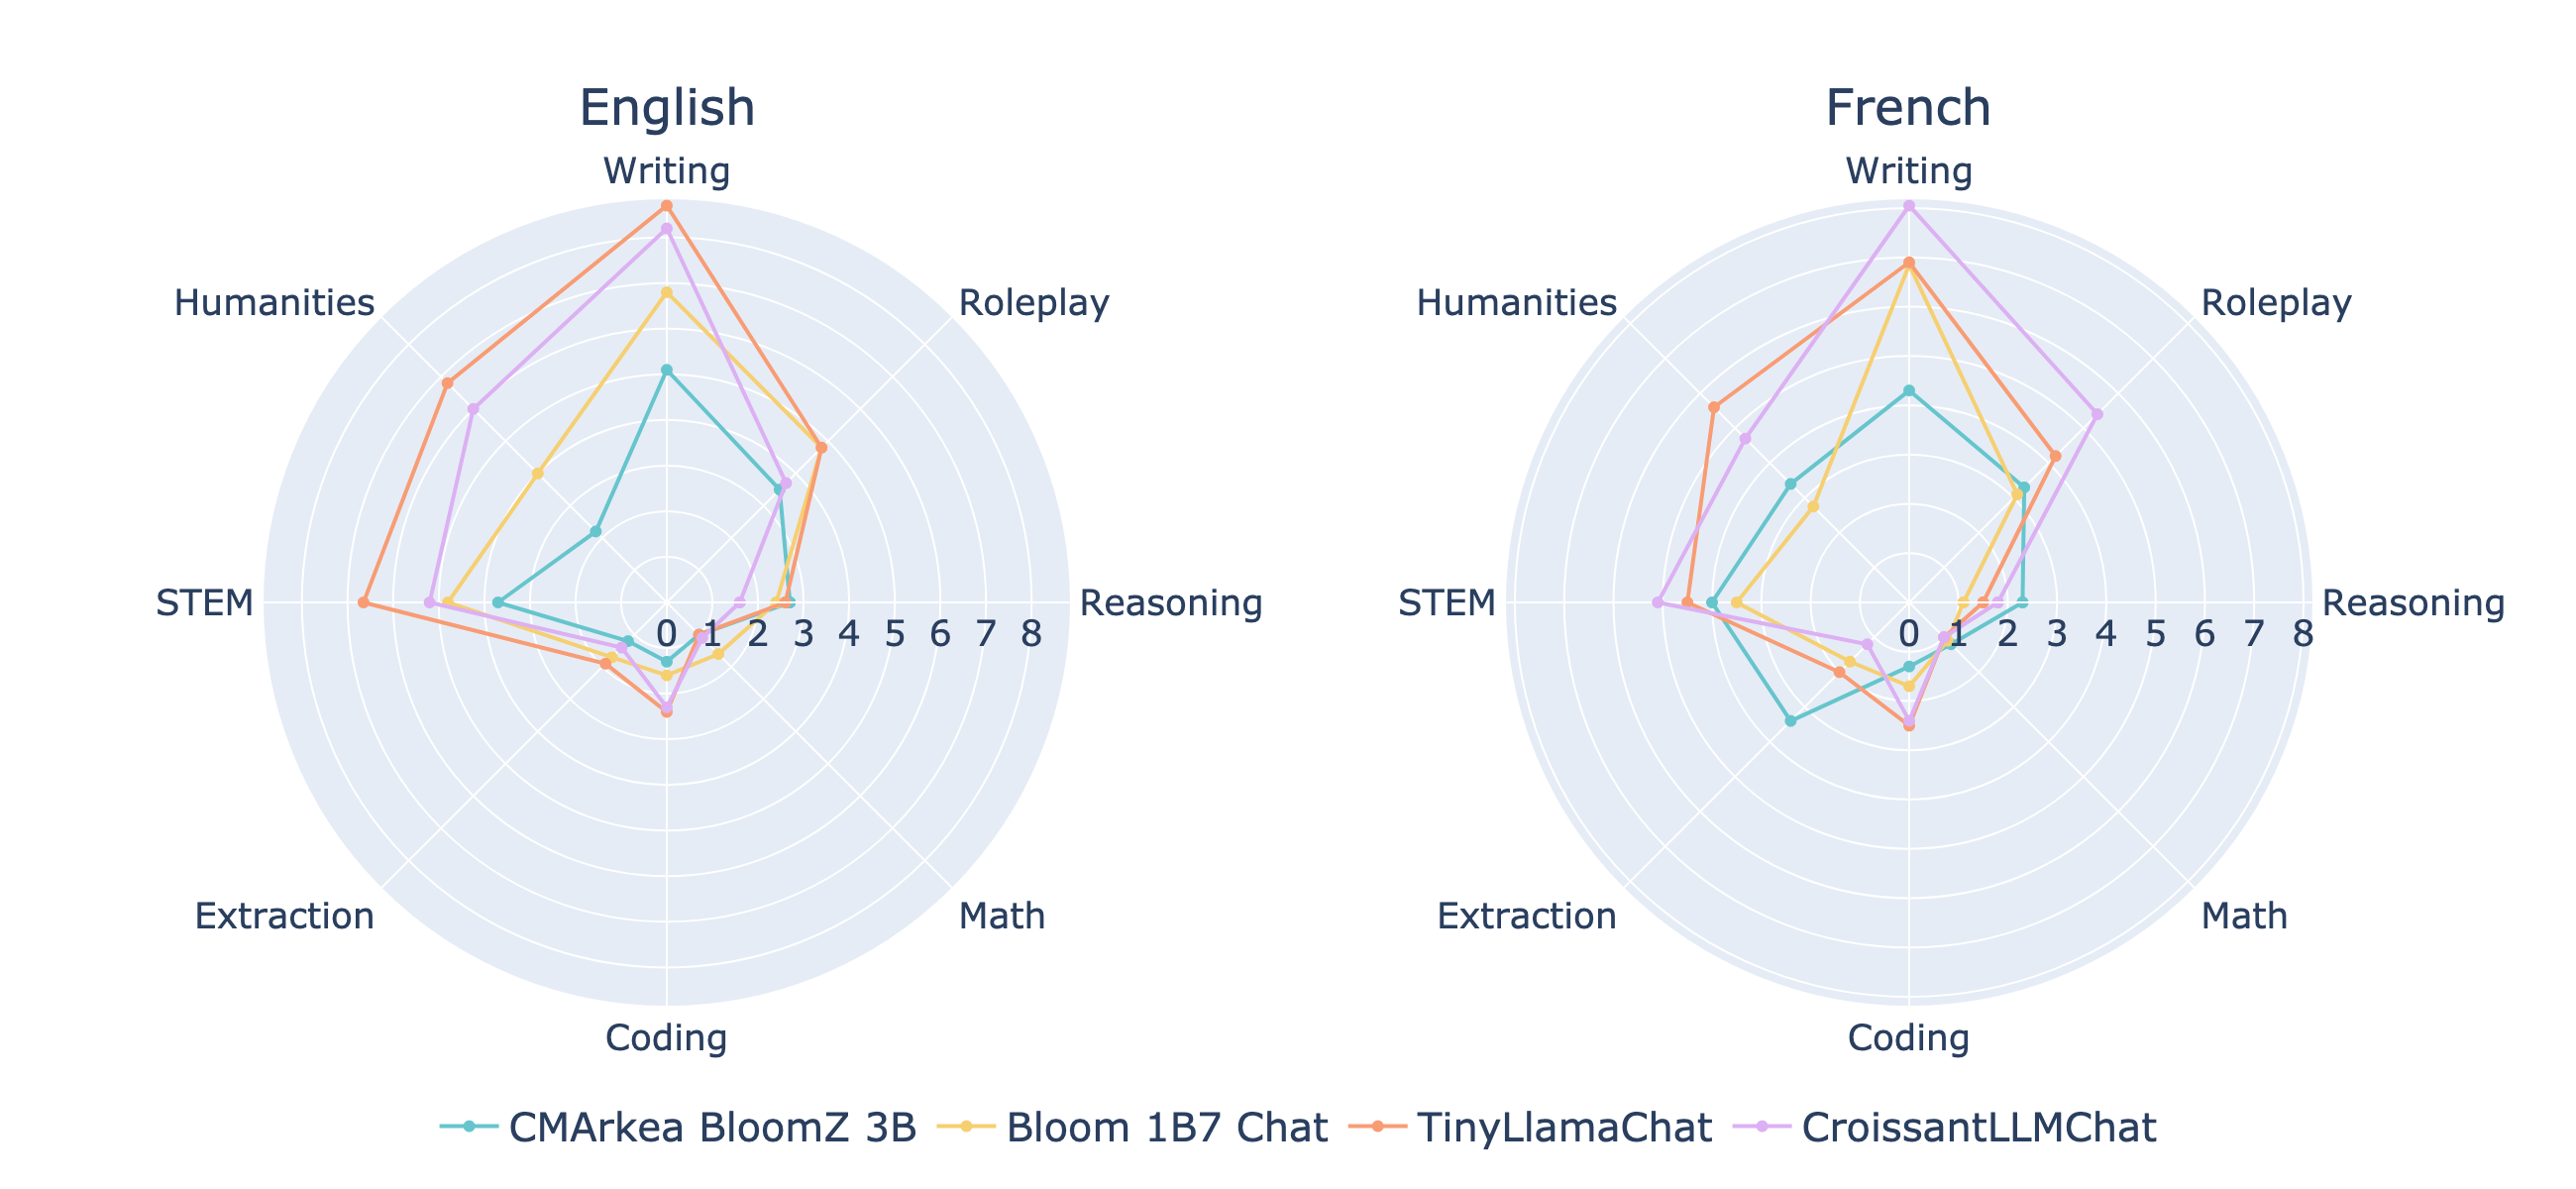
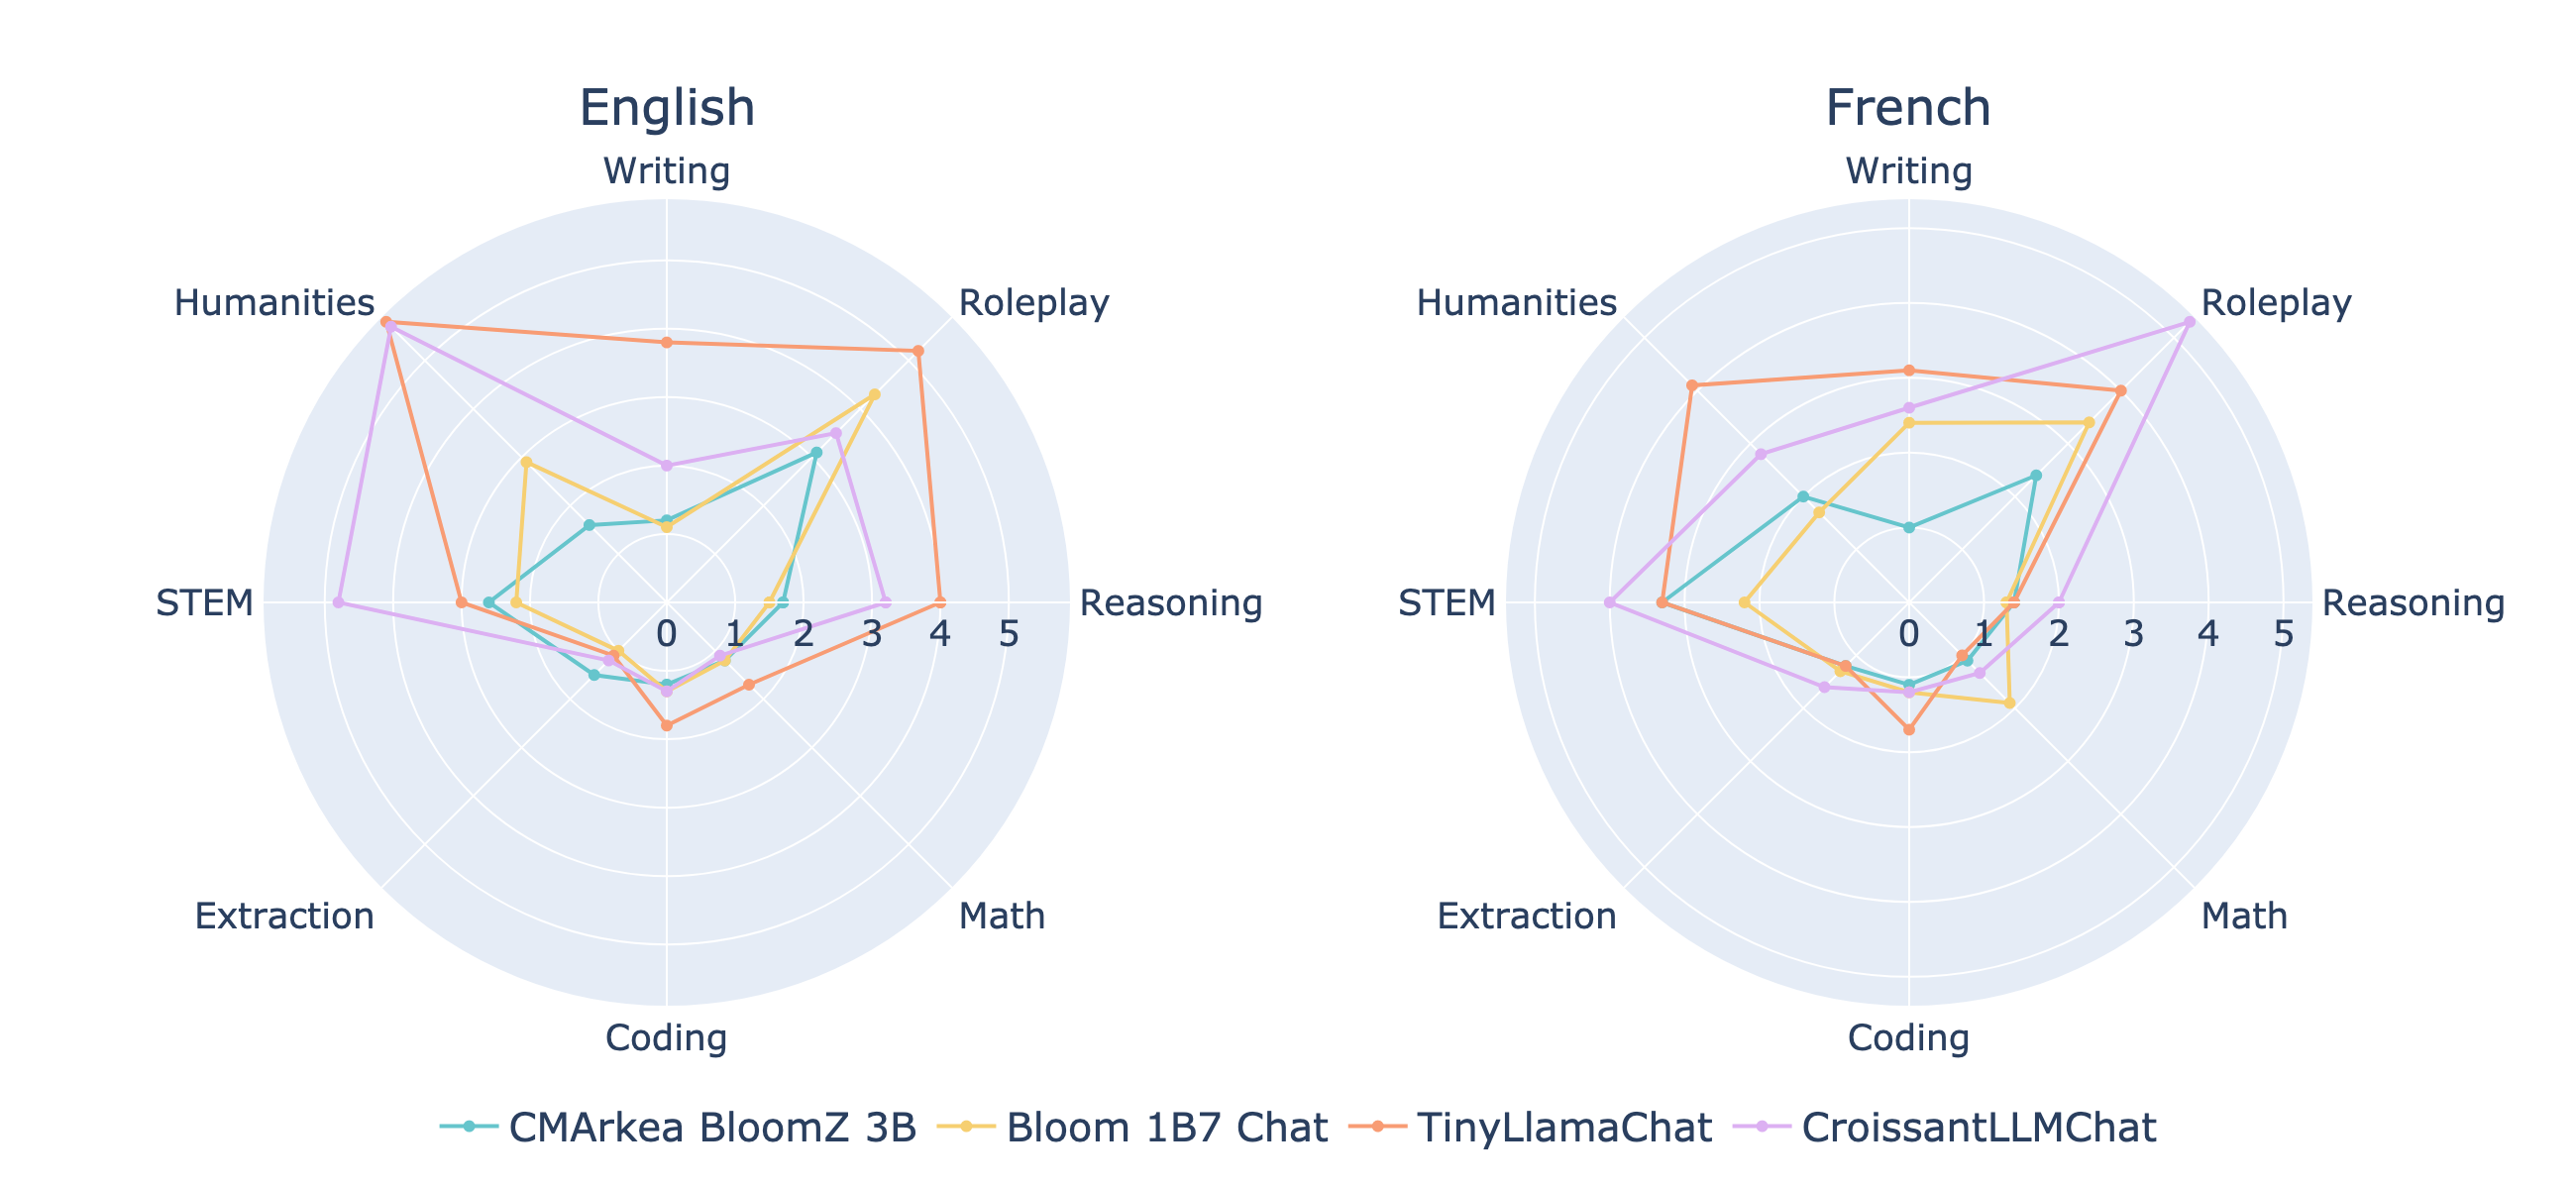
| Models | Wri | Ro | Reas | Math | Cod | Ext | STEM | Hum | Avg |
| CroissantLLMChat | 5.32 | 5.35 | 1.9 | 1.16 | 1.8 | 1.4 | 4.55 | 3.75 | 3.15 |
| TinyLlamaChat | 5 | 4.1 | 1.45 | 1 | 2.1 | 1.6 | 3.9 | 4.85 | 3 |
| Bloom 1B7 Chat | 4.62 | 3.25 | 1.2 | 1.5 | 1.45 | 1.5 | 2.85 | 2.22 | 2.32 |
| CMArkea BloomZ 3B | 2.65 | 2.85 | 1.85 | 1.15 | 1.2 | 2.3 | 3.65 | 2.7 | 2.29 |
| Vigostral 7B Chat | 7.7 | 7.85 | 4.85 | 3.65 | 4.65 | 7.75 | 7.35 | 9.2 | 6.62 |
| Vigogne 2 7b Chat | 5.35 | 6.25 | 2.75 | 2.2 | 2.47 | 3.4 | 6.05 | 6.68 | 4.39 |
| OpenHermes Mistral 7B | 8.8 | 7.5 | 5.1 | 4.05 | 5.55 | 6.2 | 8.35 | 9.4 | 6.87 |
| Vigogne 2 70B Chat | 9.4 | 8.25 | 4.75 | 4.3 | 5.35 | 7.25 | 9.1 | 9.43 | 7.23 |
| Mixtral 8x7b Instruct | 9.65 | 8.88 | 6.95 | 4.95 | 4.6 | 8.55 | 9.5 | 9.6 | 7.84 |
| Mistral Medium | 9.6 | 9.05 | 5.4 | 6.1 | 7.35 | 9.25 | 9.3 | 9.75 | 8.23 |
| GPT 3.5 Turbo | 8.75 | 8.93 | 5.05 | 5.65 | 7.85 | 9.05 | 9.05 | 9.68 | 8 |
| GPT 4 | 9.6 | 9.65 | 8.55 | 8.5 | 8.35 | 9.2 | 9.85 | 9.88 | 9.2 |
| Models | Wri | Ro | Reas | Math | Cod | Ext | STEM | Hum | Avg |
| CroissantLLMChat | 5.1 | 3.6 | 2.4 | 1.1 | 1.8 | 1.3 | 5 | 5.85 | 3.27 |
| TinyLlamaChat | 6.25 | 5 | 3.3 | 1.35 | 2.1 | 1.5 | 4.82 | 6.3 | 3.83 |
| Bloom 1B7 Chat | 3.95 | 4.55 | 1.95 | 1.4 | 1.45 | 1.35 | 3.5 | 3.45 | 2.7 |
| CMArkea BloomZ 3B | 3.15 | 3.3 | 2.2 | 1.1 | 1.25 | 1.35 | 3.15 | 1.9 | 2.17 |
| Llama 2 7B Chat | 8.9 | 7.7 | 4.25 | 2.4 | 3 | 6.5 | 8.65 | 8.75 | 6.27 |
| Vicuna 7B v1.3 | 8.1 | 7.45 | 4.65 | 2.3 | 3.55 | 5 | 7.82 | 9.1 | 6 |
| Llama 2 13B Chat | 8.85 | 7.5 | 5.1 | 3.45 | 3 | 6.92 | 8.62 | 9.75 | 6.65 |
| Vicuna 13B v1.3 | 9.25 | 7.18 | 5.85 | 2.6 | 3.25 | 5.55 | 7.98 | 9.45 | 6.39 |
| Vicuna 33B v1.3 | 9.5 | 8.45 | 6.65 | 3.15 | 3.35 | 7.1 | 8.98 | 9.8 | 7.12 |
| Llama 2 70B Chat | 9.3 | 7.5 | 5.8 | 3.3 | 3.15 | 7.25 | 8.93 | 9.62 | 6.86 |
| GPT 3.5 Turbo | 9.2 | 8.4 | 5.65 | 6.3 | 6.9 | 8.85 | 8.7 | 9.55 | 7.94 |
| GPT 4 | 9.65 | 8.9 | 9 | 6.8 | 8.55 | 9.38 | 9.7 | 9.95 | 8.99 |
Bias Assessment
We assess bias through CROWS , the Crowdsourced Stereotype Pairs benchmark that cover stereotypes dealing with nine types of bias, like race, religion, and age and report results in Table 7. We find CroissantLLM is in line, or slightly less biased than other models, notably in French.
| Task | Crows(en) | Crows(Fr) | Avg |
| mGPT(1.3B) | 3.16 | 2.94 | 3.05 |
| Bloom(3B) | 3.39 | 3.02 | 3.21 |
| Bloom(1.1B) | 3.36 | 3.07 | 3.22 |
| CroissantLLM | 3.56 | 3.22 | 3.39 |
| Pythia(1.4b) | 3.36 | 3.62 | 3.49 |
| OPT(1.3b) | 3.35 | 3.67 | 3.51 |
| TinyLlama(1.1B) | 3.48 | 3.76 | 3.62 |
| GPT-fr(1B) | 4.50 | 2.97 | 3.73 |
| Llama2(7B) | 3.72 | 3.81 | 3.76 |
MMLU Results
The MMLU benchmark has become standard in evaluating Large Language Model knowledge and reasoning capabilities. However, it is still currently very challenging for smaller models, and even very recent pretrained models such as Llama 3.2(1B) or Gemma2 report base model performances that are only slightly better than random (. CroissantLLM, TinyLlama, and other small model baselines in this paper display random performance on the task ( which is why the task is not included in the main paper.
References
- Leo Gao, Jonathan Tow, Stella Biderman, Sid Black, Anthony DiPofi, Charles Foster, Laurence Golding, Jeffrey Hsu, Kyle McDonell, Niklas Muennighoff, Jason Phang, Laria Reynolds, Eric Tang, Anish Thite, Ben Wang, Kevin Wang, Andy Zou (2021). A framework for few-shot language model evaluation. Zenodo. Source ↗
- Nikita Nangia, Clara Vania, Rasika Bhalerao, Samuel R. Bowman (2020). CrowS-Pairs: A Challenge Dataset for Measuring Social Biases in Masked Language Models.
- Aurélie Névéol, Yoann Dupont, Julien Bezançon, Karën Fort (2022). French CrowS-Pairs: Extension à une langue autre que l'anglais d'un corpus de mesure des biais sociétaux dans les modèles de langue masqués (French CrowS-Pairs : Extending a challenge dataset for measuring social bias in masked language models to a language other than English). Actes de la 29e Conférence sur le Traitement Automatique des Langues Naturelles. Volume 1 : conférence principale. Source ↗
- Dan Hendrycks, Collin Burns, Steven Basart, Andy Zou, Mantas Mazeika, Dawn Song, Jacob Steinhardt (2020). Measuring Massive Multitask Language Understanding. arXiv. Source ↗
- Abhimanyu Dubey, Abhinav Jauhri, Abhinav Pandey, Abhishek Kadian, Ahmad Al-Dahle, Aiesha Letman, Akhil Mathur, Alan Schelten, Amy Yang, Angela Fan, Anirudh Goyal, Anthony Hartshorn, Aobo Yang, Archi Mitra, Archie Sravankumar, Artem Korenev, Arthur Hinsvark, Arun Rao, Aston Zhang, Aurelien Rodriguez, Austen Gregerson, Ava Spataru, Baptiste Roziere, Bethany Biron, Binh Tang, Bobbie Chern, Charlotte Caucheteux, Chaya Nayak, Chloe Bi, Chris Marra, Chris McConnell, Christian Keller, Christophe Touret, Chunyang Wu, Corinne Wong, Cristian Canton Ferrer, Cyrus Nikolaidis, Damien Allonsius, Daniel Song, Danielle Pintz, Danny Livshits, David Esiobu, Dhruv Choudhary, Dhruv Mahajan, Diego Garcia-Olano, Diego Perino, Dieuwke Hupkes, Egor Lakomkin, Ehab AlBadawy, Elina Lobanova, Emily Dinan, Eric Michael Smith, Filip Radenovic, Frank Zhang, Gabriel Synnaeve, Gabrielle Lee, Georgia Lewis Anderson, Graeme Nail, Gregoire Mialon, Guan Pang, Guillem Cucurell, Hailey Nguyen, Hannah Korevaar, Hu Xu, Hugo Touvron, Iliyan Zarov, Imanol Arrieta Ibarra, Isabel Kloumann, Ishan Misra, Ivan Evtimov, Jade Copet, Jaewon Lee, Jan Geffert, Jana Vranes, Jason Park, Jay Mahadeokar, Jeet Shah, Jelmer van der Linde, Jennifer Billock, Jenny Hong, Jenya Lee, Jeremy Fu, Jianfeng Chi, Jianyu Huang, Jiawen Liu, Jie Wang, Jiecao Yu, Joanna Bitton, Joe Spisak, Jongsoo Park, Joseph Rocca, Joshua Johnstun, Joshua Saxe, Junteng Jia, Kalyan Vasuden Alwala, Kartikeya Upasani, Kate Plawiak, Ke Li, Kenneth Heafield, Kevin Stone, Khalid El-Arini, Krithika Iyer, Kshitiz Malik, Kuenley Chiu, Kunal Bhalla, Lauren Rantala-Yeary, Laurens van der Maaten, Lawrence Chen, Liang Tan, Liz Jenkins, Louis Martin, Lovish Madaan, Lubo Malo, Lukas Blecher, Lukas Landzaat, Luke de Oliveira, Madeline Muzzi, Mahesh Pasupuleti, Mannat Singh, Manohar Paluri, Marcin Kardas, Mathew Oldham, Mathieu Rita, Maya Pavlova, Melanie Kambadur, Mike Lewis, Min Si, Mitesh Kumar Singh, Mona Hassan, Naman Goyal, Narjes Torabi, Nikolay Bashlykov, Nikolay Bogoychev, Niladri Chatterji, Olivier Duchenne, Onur Çelebi, Patrick Alrassy, Pengchuan Zhang, Pengwei Li, Petar Vasic, Peter Weng, Prajjwal Bhargava, Pratik Dubal, Praveen Krishnan, Punit Singh Koura, Puxin Xu, Qing He, Qingxiao Dong, Ragavan Srinivasan, Raj Ganapathy, Ramon Calderer, Ricardo Silveira Cabral, Robert Stojnic, Roberta Raileanu, Rohit Girdhar, Rohit Patel, Romain Sauvestre, Ronnie Polidoro, Roshan Sumbaly, Ross Taylor, Ruan Silva, Rui Hou, Rui Wang, Saghar Hosseini, Sahana Chennabasappa, Sanjay Singh, Sean Bell, Seohyun Sonia Kim, Sergey Edunov, Shaoliang Nie, Sharan Narang, Sharath Raparthy, Sheng Shen, Shengye Wan, Shruti Bhosale, Shun Zhang, Simon Vandenhende, Soumya Batra, Spencer Whitman, Sten Sootla, Stephane Collot, Suchin Gururangan, Sydney Borodinsky, Tamar Herman, Tara Fowler, Tarek Sheasha, Thomas Georgiou, Thomas Scialom, Tobias Speckbacher, Todor Mihaylov, Tong Xiao, Ujjwal Karn, Vedanuj Goswami, Vibhor Gupta, Vignesh Ramanathan, Viktor Kerkez, Vincent Gonguet, Virginie Do, Vish Vogeti, Vladan Petrovic, Weiwei Chu, Wenhan Xiong, Wenyin Fu, Whitney Meers, Xavier Martinet, Xiaodong Wang, Xiaoqing Ellen Tan, Xinfeng Xie, Xuchao Jia, Xuewei Wang, Yaelle Goldschlag, Yashesh Gaur, Yasmine Babaei, Yi Wen, Yiwen Song, Yuchen Zhang, Yue Li, Yuning Mao, Zacharie Delpierre Coudert, Zheng Yan, Zhengxing Chen, Zoe Papakipos, Aaditya Singh, Aaron Grattafiori, Abha Jain, Adam Kelsey, Adam Shajnfeld, Adithya Gangidi, Adolfo Victoria, Ahuva Goldstand, Ajay Menon, Ajay Sharma, Alex Boesenberg, Alex Vaughan, Alexei Baevski, Allie Feinstein, Amanda Kallet, Amit Sangani, Anam Yunus, Andrei Lupu, Andres Alvarado, Andrew Caples, Andrew Gu, Andrew Ho, Andrew Poulton, Andrew Ryan, Ankit Ramchandani, Annie Franco, Aparajita Saraf, Arkabandhu Chowdhury, Ashley Gabriel, Ashwin Bharambe, Assaf Eisenman, Azadeh Yazdan, Beau James, Ben Maurer, Benjamin Leonhardi, Bernie Huang, Beth Loyd, Beto De Paola, Bhargavi Paranjape, Bing Liu, Bo Wu, Boyu Ni, Braden Hancock, Bram Wasti, Brandon Spence, Brani Stojkovic, Brian Gamido, Britt Montalvo, Carl Parker, Carly Burton, Catalina Mejia, Changhan Wang, Changkyu Kim, Chao Zhou, Chester Hu, Ching-Hsiang Chu, Chris Cai, Chris Tindal, Christoph Feichtenhofer, Damon Civin, Dana Beaty, Daniel Kreymer, Daniel Li, Danny Wyatt, David Adkins, David Xu, Davide Testuggine, Delia David, Devi Parikh, Diana Liskovich, Didem Foss, Dingkang Wang, Duc Le, Dustin Holland, Edward Dowling, Eissa Jamil, Elaine Montgomery, Eleonora Presani, Emily Hahn, Emily Wood, Erik Brinkman, Esteban Arcaute, Evan Dunbar, Evan Smothers, Fei Sun, Felix Kreuk, Feng Tian, Firat Ozgenel, Francesco Caggioni, Francisco Guzmán, Frank Kanayet, Frank Seide, Gabriela Medina Florez, Gabriella Schwarz, Gada Badeer, Georgia Swee, Gil Halpern, Govind Thattai, Grant Herman, Grigory Sizov, Guangyi, Zhang, Guna Lakshminarayanan, Hamid Shojanazeri, Han Zou, Hannah Wang, Hanwen Zha, Haroun Habeeb, Harrison Rudolph, Helen Suk, Henry Aspegren, Hunter Goldman, Ibrahim Damlaj, Igor Molybog, Igor Tufanov, Irina-Elena Veliche, Itai Gat, Jake Weissman, James Geboski, James Kohli, Japhet Asher, Jean-Baptiste Gaya, Jeff Marcus, Jeff Tang, Jennifer Chan, Jenny Zhen, Jeremy Reizenstein, Jeremy Teboul, Jessica Zhong, Jian Jin, Jingyi Yang, Joe Cummings, Jon Carvill, Jon Shepard, Jonathan McPhie, Jonathan Torres, Josh Ginsburg, Junjie Wang, Kai Wu, Kam Hou U, Karan Saxena, Karthik Prasad, Kartikay Khandelwal, Katayoun Zand, Kathy Matosich, Kaushik Veeraraghavan, Kelly Michelena, Keqian Li, Kun Huang, Kunal Chawla, Kushal Lakhotia, Kyle Huang, Lailin Chen, Lakshya Garg, Lavender A, Leandro Silva, Lee Bell, Lei Zhang, Liangpeng Guo, Licheng Yu, Liron Moshkovich, Luca Wehrstedt, Madian Khabsa, Manav Avalani, Manish Bhatt, Maria Tsimpoukelli, Martynas Mankus, Matan Hasson, Matthew Lennie, Matthias Reso, Maxim Groshev, Maxim Naumov, Maya Lathi, Meghan Keneally, Michael L. Seltzer, Michal Valko, Michelle Restrepo, Mihir Patel, Mik Vyatskov, Mikayel Samvelyan, Mike Clark, Mike Macey, Mike Wang, Miquel Jubert Hermoso, Mo Metanat, Mohammad Rastegari, Munish Bansal, Nandhini Santhanam, Natascha Parks, Natasha White, Navyata Bawa, Nayan Singhal, Nick Egebo, Nicolas Usunier, Nikolay Pavlovich Laptev, Ning Dong, Ning Zhang, Norman Cheng, Oleg Chernoguz, Olivia Hart, Omkar Salpekar, Ozlem Kalinli, Parkin Kent, Parth Parekh, Paul Saab, Pavan Balaji, Pedro Rittner, Philip Bontrager, Pierre Roux, Piotr Dollar, Polina Zvyagina, Prashant Ratanchandani, Pritish Yuvraj, Qian Liang, Rachad Alao, Rachel Rodriguez, Rafi Ayub, Raghotham Murthy, Raghu Nayani, Rahul Mitra, Raymond Li, Rebekkah Hogan, Robin Battey, Rocky Wang, Rohan Maheswari, Russ Howes, Ruty Rinott, Sai Jayesh Bondu, Samyak Datta, Sara Chugh, Sara Hunt, Sargun Dhillon, Sasha Sidorov, Satadru Pan, Saurabh Verma, Seiji Yamamoto, Sharadh Ramaswamy, Shaun Lindsay, Shaun Lindsay, Sheng Feng, Shenghao Lin, Shengxin Cindy Zha, Shiva Shankar, Shuqiang Zhang, Shuqiang Zhang, Sinong Wang, Sneha Agarwal, Soji Sajuyigbe, Soumith Chintala, Stephanie Max, Stephen Chen, Steve Kehoe, Steve Satterfield, Sudarshan Govindaprasad, Sumit Gupta, Sungmin Cho, Sunny Virk, Suraj Subramanian, Sy Choudhury, Sydney Goldman, Tal Remez, Tamar Glaser, Tamara Best, Thilo Kohler, Thomas Robinson, Tianhe Li, Tianjun Zhang, Tim Matthews, Timothy Chou, Tzook Shaked, Varun Vontimitta, Victoria Ajayi, Victoria Montanez, Vijai Mohan, Vinay Satish Kumar, Vishal Mangla, Vítor Albiero, Vlad Ionescu, Vlad Poenaru, Vlad Tiberiu Mihailescu, Vladimir Ivanov, Wei Li, Wenchen Wang, Wenwen Jiang, Wes Bouaziz, Will Constable, Xiaocheng Tang, Xiaofang Wang, Xiaojian Wu, Xiaolan Wang, Xide Xia, Xilun Wu, Xinbo Gao, Yanjun Chen, Ye Hu, Ye Jia, Ye Qi, Yenda Li, Yilin Zhang, Ying Zhang, Yossi Adi, Youngjin Nam, Yu, Wang, Yuchen Hao, Yundi Qian, Yuzi He, Zach Rait, Zachary DeVito, Zef Rosnbrick, Zhaoduo Wen, Zhenyu Yang, Zhiwei Zhao (2024). The Llama 3 Herd of Models. Source ↗
- Gemma Team, Morgane Riviere, Shreya Pathak, Pier Giuseppe Sessa, Cassidy Hardin, Surya Bhupatiraju, Léonard Hussenot, Thomas Mesnard, Bobak Shahriari, Alexandre Ramé, Johan Ferret, Peter Liu, Pouya Tafti, Abe Friesen, Michelle Casbon, Sabela Ramos, Ravin Kumar, Charline Le Lan, Sammy Jerome, Anton Tsitsulin, Nino Vieillard, Piotr Stanczyk, Sertan Girgin, Nikola Momchev, Matt Hoffman, Shantanu Thakoor, Jean-Bastien Grill, Behnam Neyshabur, Olivier Bachem, Alanna Walton, Aliaksei Severyn, Alicia Parrish, Aliya Ahmad, Allen Hutchison, Alvin Abdagic, Amanda Carl, Amy Shen, Andy Brock, Andy Coenen, Anthony Laforge, Antonia Paterson, Ben Bastian, Bilal Piot, Bo Wu, Brandon Royal, Charlie Chen, Chintu Kumar, Chris Perry, Chris Welty, Christopher A. Choquette-Choo, Danila Sinopalnikov, David Weinberger, Dimple Vijaykumar, Dominika Rogozińska, Dustin Herbison, Elisa Bandy, Emma Wang, Eric Noland, Erica Moreira, Evan Senter, Evgenii Eltyshev, Francesco Visin, Gabriel Rasskin, Gary Wei, Glenn Cameron, Gus Martins, Hadi Hashemi, Hanna Klimczak-Plucińska, Harleen Batra, Harsh Dhand, Ivan Nardini, Jacinda Mein, Jack Zhou, James Svensson, Jeff Stanway, Jetha Chan, Jin Peng Zhou, Joana Carrasqueira, Joana Iljazi, Jocelyn Becker, Joe Fernandez, Joost van Amersfoort, Josh Gordon, Josh Lipschultz, Josh Newlan, Ju-yeong Ji, Kareem Mohamed, Kartikeya Badola, Kat Black, Katie Millican, Keelin McDonell, Kelvin Nguyen, Kiranbir Sodhia, Kish Greene, Lars Lowe Sjoesund, Lauren Usui, Laurent Sifre, Lena Heuermann, Leticia Lago, Lilly McNealus, Livio Baldini Soares, Logan Kilpatrick, Lucas Dixon, Luciano Martins, Machel Reid, Manvinder Singh, Mark Iverson, Martin Görner, Mat Velloso, Mateo Wirth, Matt Davidow, Matt Miller, Matthew Rahtz, Matthew Watson, Meg Risdal, Mehran Kazemi, Michael Moynihan, Ming Zhang, Minsuk Kahng, Minwoo Park, Mofi Rahman, Mohit Khatwani, Natalie Dao, Nenshad Bardoliwalla, Nesh Devanathan, Neta Dumai, Nilay Chauhan, Oscar Wahltinez, Pankil Botarda, Parker Barnes, Paul Barham, Paul Michel, Pengchong Jin, Petko Georgiev, Phil Culliton, Pradeep Kuppala, Ramona Comanescu, Ramona Merhej, Reena Jana, Reza Ardeshir Rokni, Rishabh Agarwal, Ryan Mullins, Samaneh Saadat, Sara Mc Carthy, Sarah Cogan, Sarah Perrin, Sébastien M. R. Arnold, Sebastian Krause, Shengyang Dai, Shruti Garg, Shruti Sheth, Sue Ronstrom, Susan Chan, Timothy Jordan, Ting Yu, Tom Eccles, Tom Hennigan, Tomas Kocisky, Tulsee Doshi, Vihan Jain, Vikas Yadav, Vilobh Meshram, Vishal Dharmadhikari, Warren Barkley, Wei Wei, Wenming Ye, Woohyun Han, Woosuk Kwon, Xiang Xu, Zhe Shen, Zhitao Gong, Zichuan Wei, Victor Cotruta, Phoebe Kirk, Anand Rao, Minh Giang, Ludovic Peran, Tris Warkentin, Eli Collins, Joelle Barral, Zoubin Ghahramani, Raia Hadsell, D. Sculley, Jeanine Banks, Anca Dragan, Slav Petrov, Oriol Vinyals, Jeff Dean, Demis Hassabis, Koray Kavukcuoglu, Clement Farabet, Elena Buchatskaya, Sebastian Borgeaud, Noah Fiedel, Armand Joulin, Kathleen Kenealy, Robert Dadashi, Alek Andreev (2024). Gemma 2: Improving Open Language Models at a Practical Size. Source ↗